Filterless Snapshot Hyperspectral Imaging Using Guided Patch Diffusion
Abstract
We consider the problem of reconstructing a H x W x 31 hyperspectral image from a H x W grayscale snapshot measurement that is captured using only a single diffractive lens and a filterless panchromatic photosensor. This problem is severely ill-posed, but we present a model that produces high-quality results in simulation and experiment. We make efficient use of limited training data by creating a conditional denoising diffusion model that operates on small patches in a shift-invariant manner. During inference, we synchronize per-patch hyperspectral predictions using guidance by physical consistency with the system's optical point spread function. Our experiments reveal that the patch size can be as small as the point spread function, with local optical cues being the main source of information about complete spectra. Also, by drawing multiple samples, our model provides per-pixel uncertainty estimates that strongly correlate with reconstruction error.
Video
Hyperspectral Imaging via Camera Guided Diffusion
A diffractive metasurface lens introduces purposeful chromatic aberration, smearing the spectral information from a point in the scene across many pixels at the photosensor. This produces a simple but useful optical encoding of the high-dimensional hyperspectral cube (right) to a grayscale measurement (left).
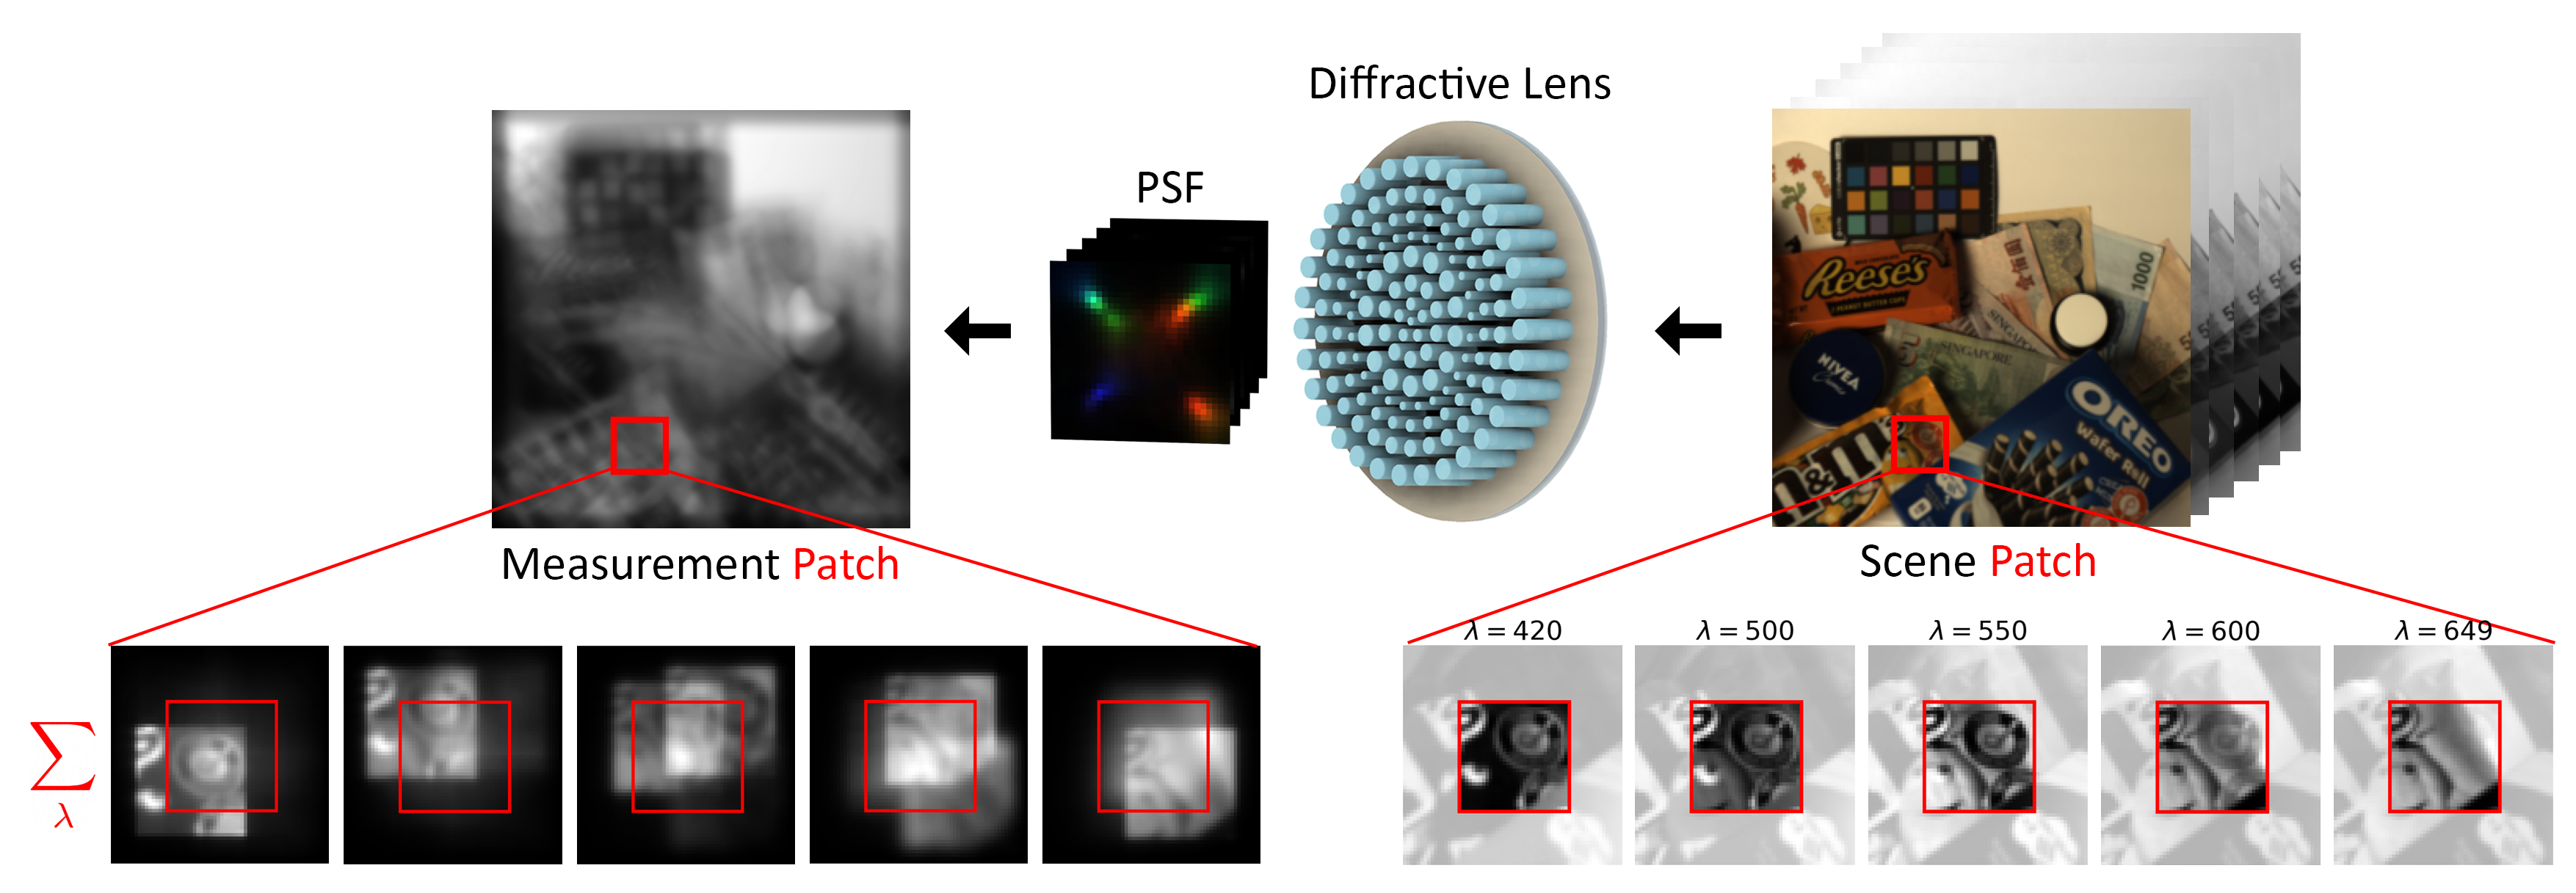
We show for the first time that the inverse, grayscale-to-hyperspectral reconstruction problem can be approximately solved without the need for complex multi-component optics or multiple measurements with spectral filters. The use of a simple lens and filterless sensor results in ambiguity where the grayscale measurement could map to many distinct but equally plausible hyperspectral cubes. Nonetheless, we obtain high quality reconstructions by leveraging a denoising diffusion model to learn the distribution of solutions.
Method Overview
We frame the reconstruction problem as a patch-to-patch translation task: a hyperspectral scene patch is optically encoded into a measurement patch by the lens, and our model learns to invert this local mapping.
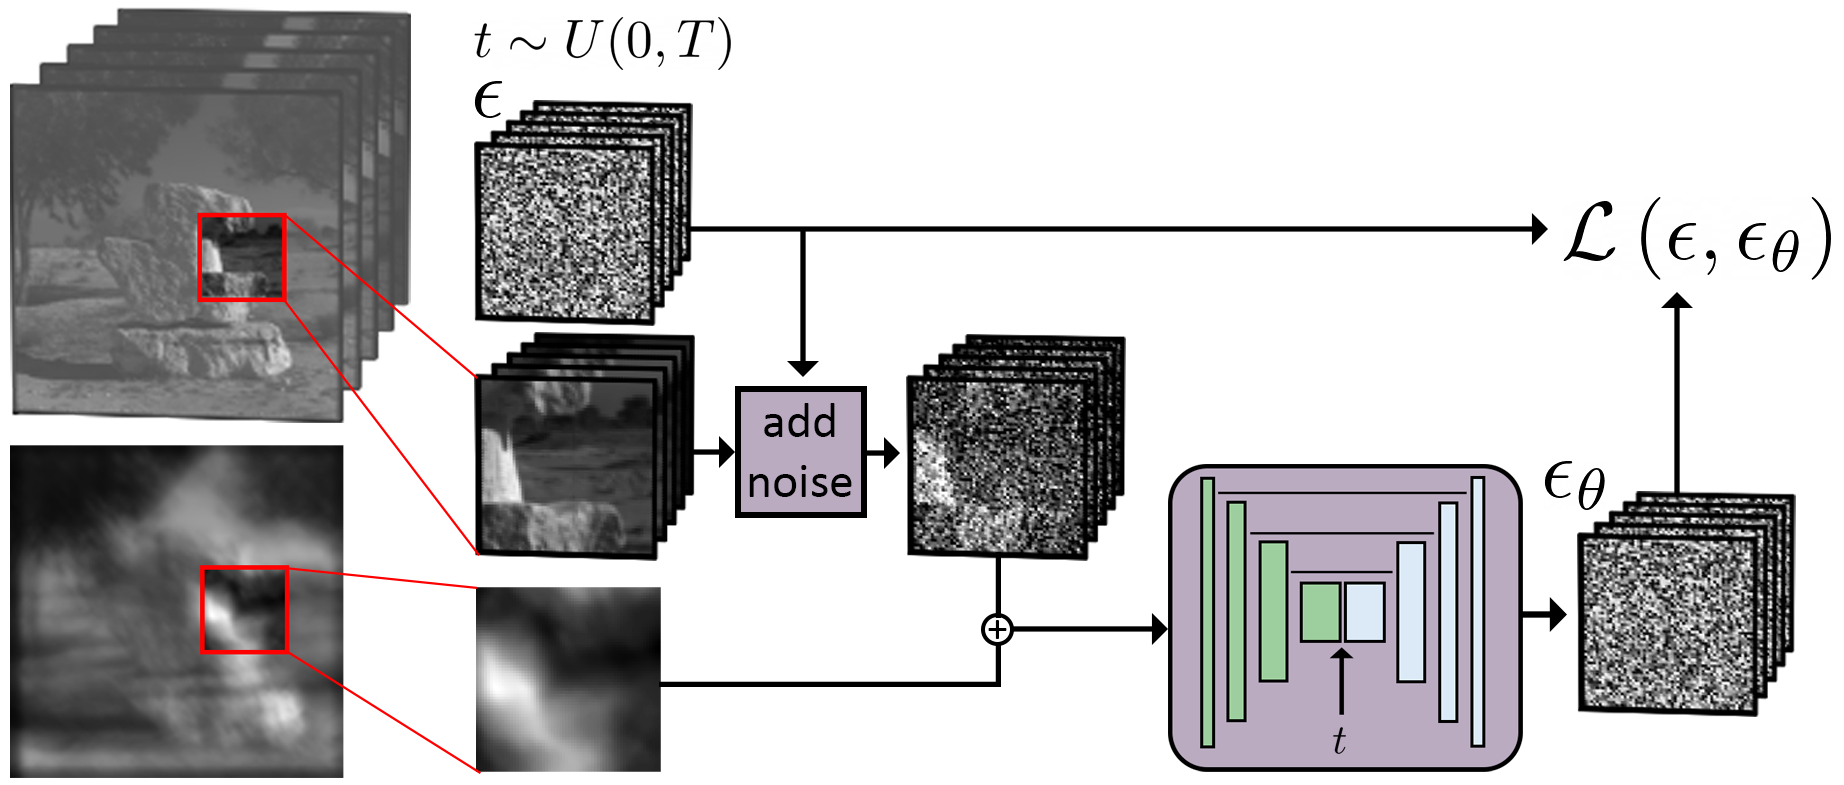
We train our diffusion model to generate small 64x64x31 hyperspectral image patches, conditioned on 64x64 pixel measurement patches. This allows us to train with limited, real HSI datasets (900 images). During training, the model learns to denoise a noised hyperspectral patch back to the clean patch, conditioned on the corresponding measurement patch, as illustrated below.
Once trained, our model is applied to reconstruct measurements of any size. This is done by splitting the measurement into patches, processing all patches in parallel, and then enforcing consistency across patch predictions at each denoising step using diffusion guidance. Our guidance enforces that the stitched, full-size hyperspectral prediction projects back to the captured measurement when rendered with the camera's known optical response.
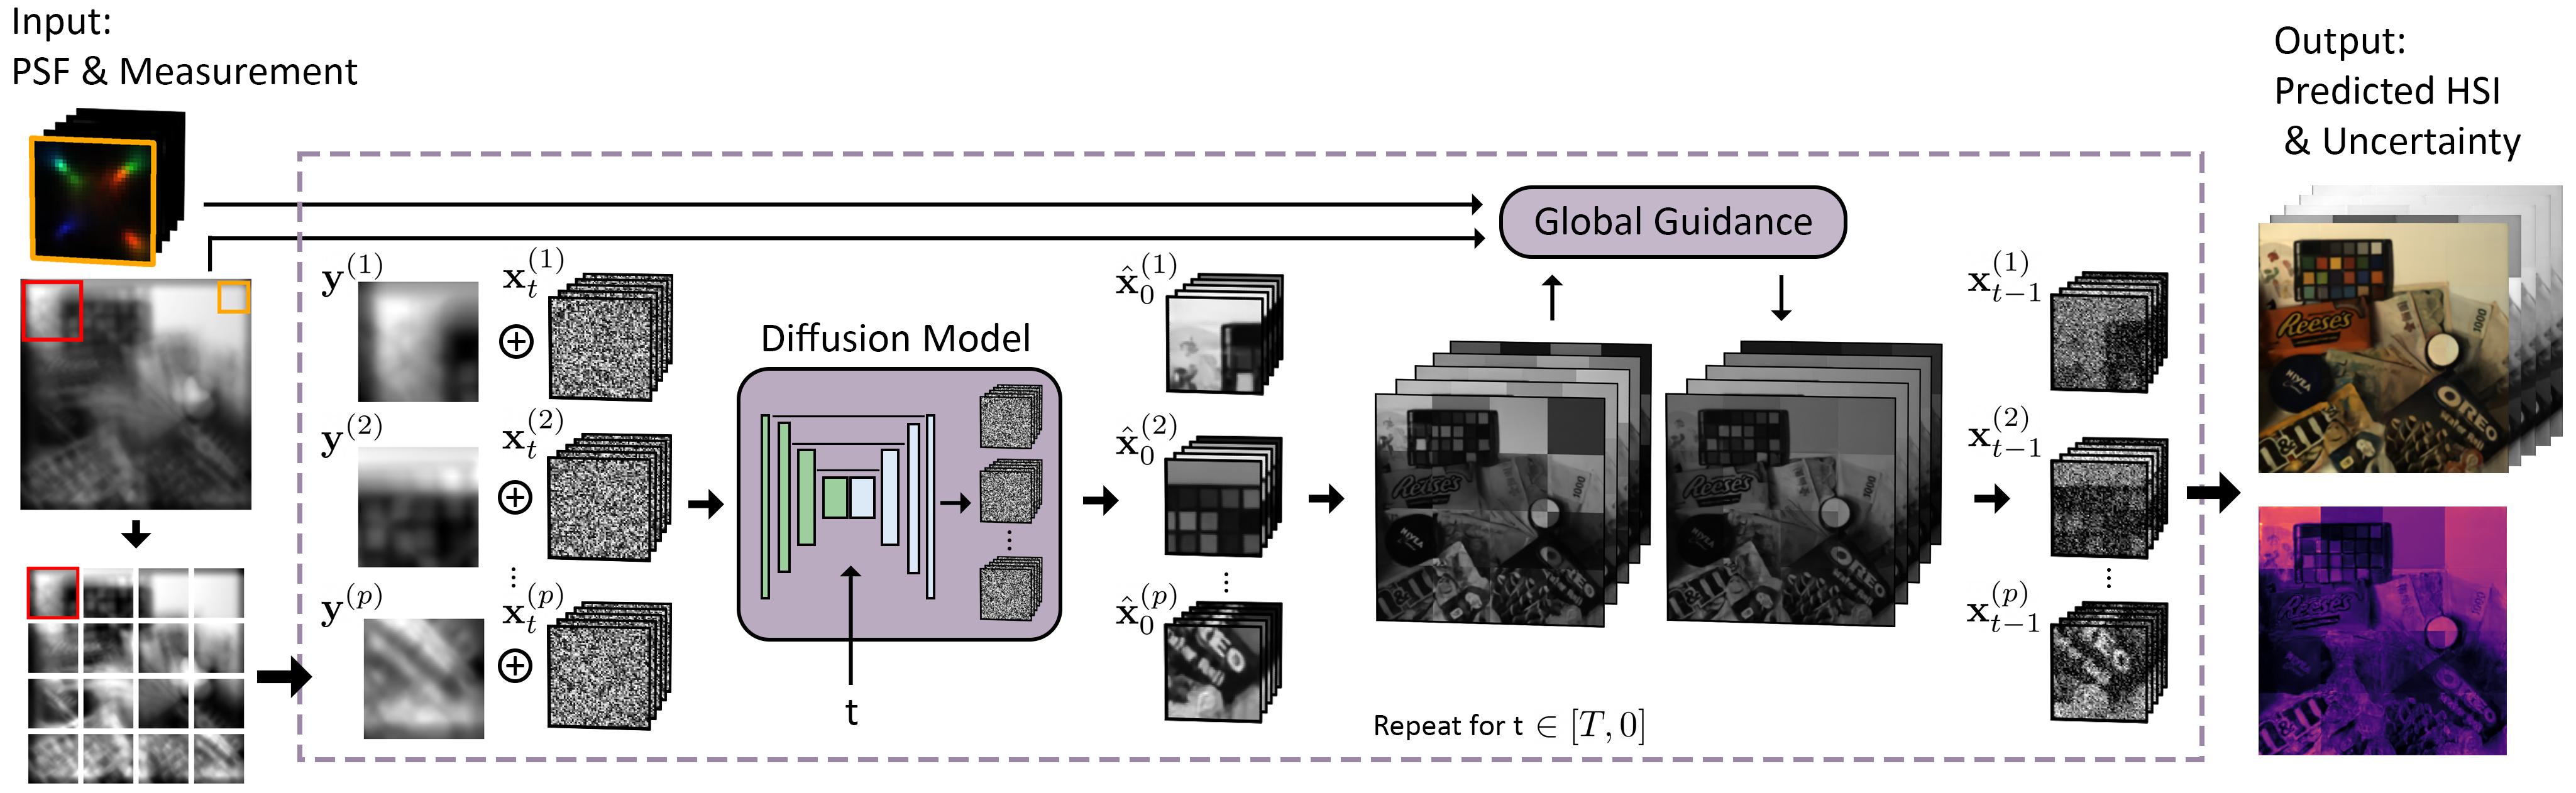
We note that the success in reconstructing hyperspectral images by processing the measurement in patches is initially surprising. The measurement is formed by a convolution with the spatially-extended point-spread function kernel. Consequently, relevant signal about a target HSI patch is partially scattered outside of the co-aligned measurement patch. In addition, extraneous signal from neighboring HSI patches is scattered into the measurement patch. This makes a patch-based reconstruction algorithm highly ill-posed. Despite this fact, we find that our patch model outperforms existing deep models that process full measurements directly. We show that there is value in concentrating neural capacities to smaller regions using a diffusion model and to instead synthesize full-size predictions by tying together the patch predictions using guidance.
HSI Reconstructions on the ARAD1K Dataset
We benchmark our algorithm against existing grayscale to hyperspectral reconstruction networks using the ARAD1K dataset. Although our patch-based model can handle measurements of any size, we first train/test on 256x256 pixel measurements to enable comparison with previous models that are limited to small images. In the paper, we demonstrate that our model can directly reconstruct larger 1280x1280 and 1280x1536 pixel measurements. Additional studies are discussed in the paper, considering RGB filters and different optics used to capture measurements.
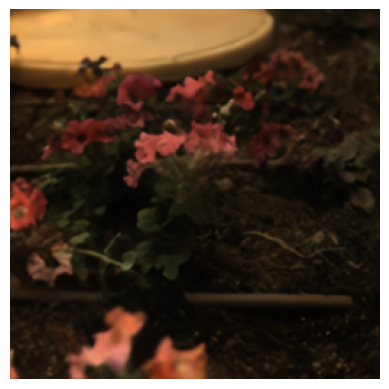
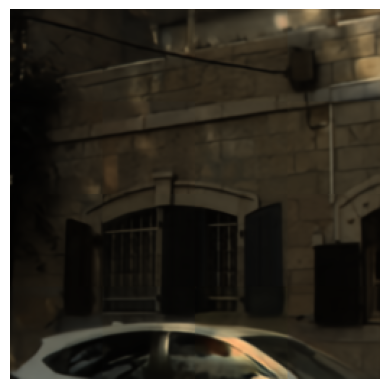
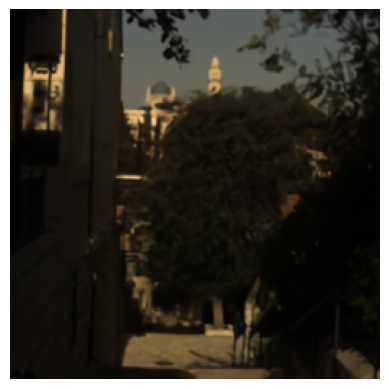
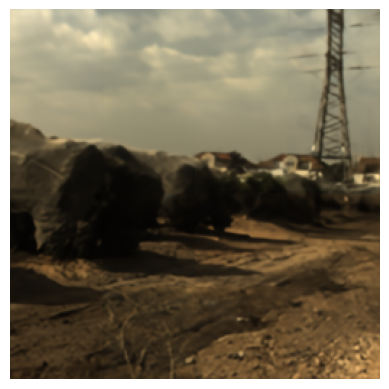
In the sliders below, we show the rendered grayscale measurements that are used as conditioning for our diffusion model. Each measurement is simulated using the metasurface lens and has significant chromatic aberration. To reconstruct a prediction of the true hyperspectral images, each measurement is split into 16 64x64 pixel patches during inference time and processed in parallel. The reconstructed hyperspectral image is visualized projected to RGB colorspace. We are able to restore fine spatial features and dense spectral information for every pixel, using only simple optical cues.

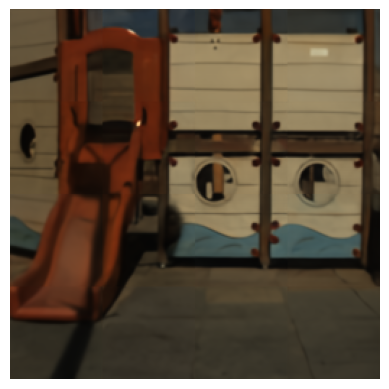
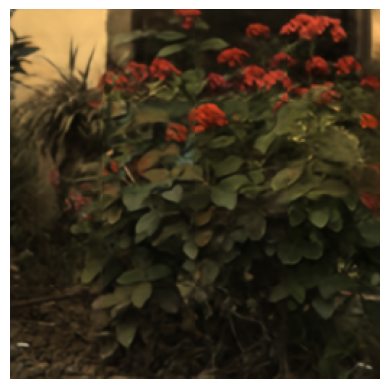
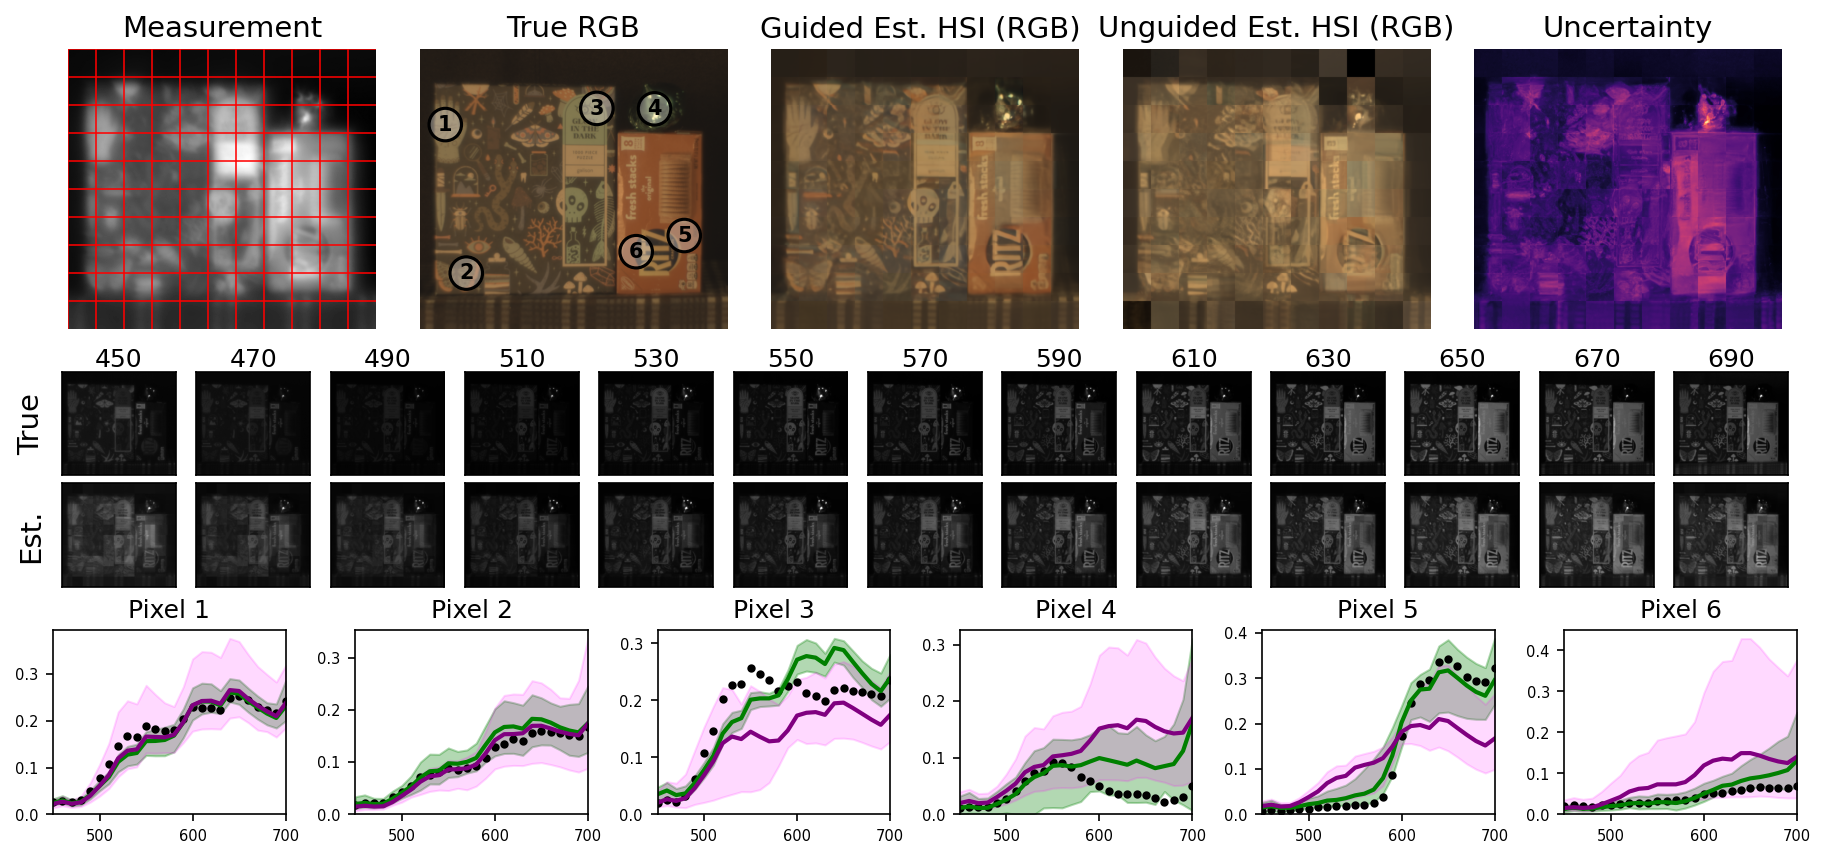
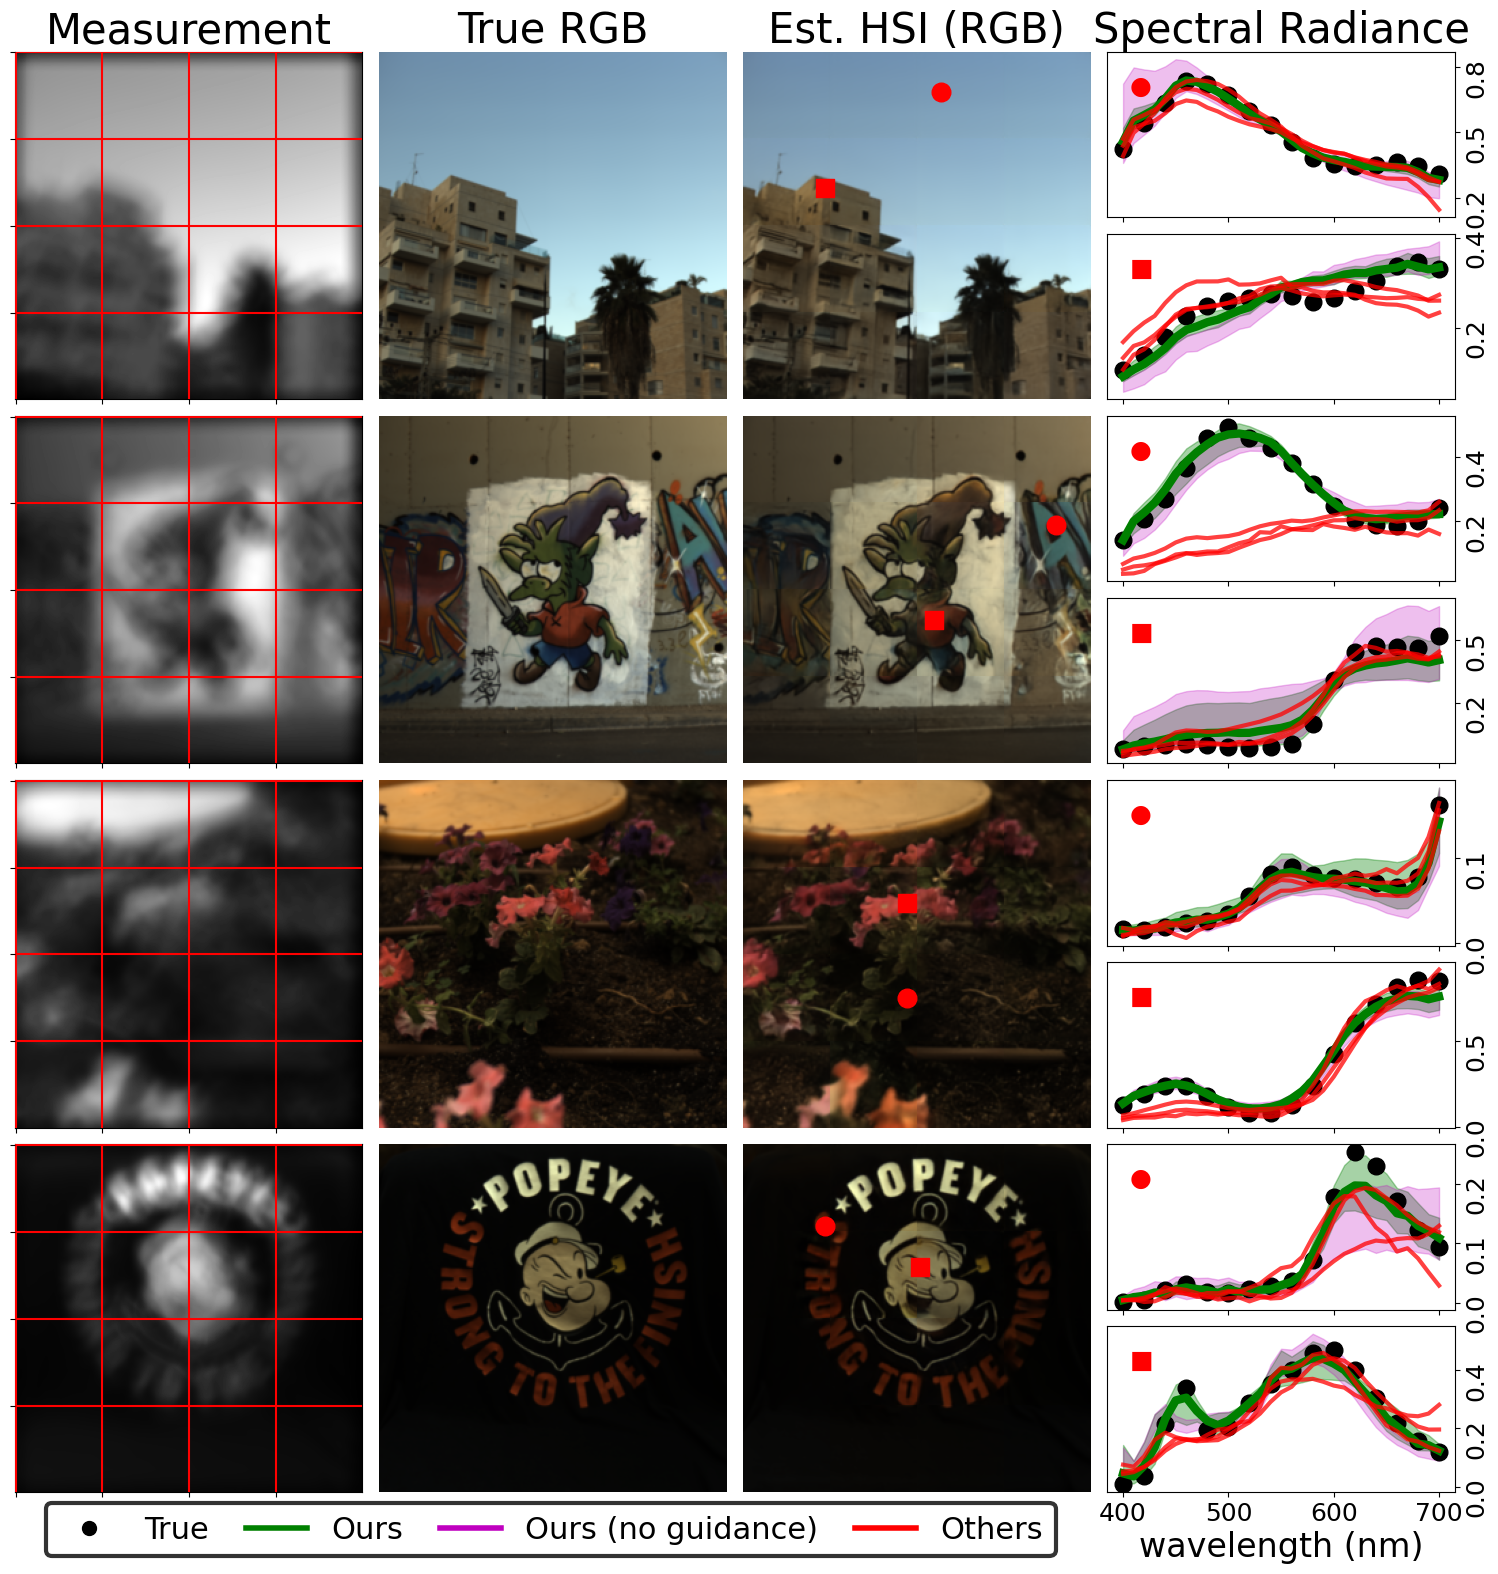
We further evaluate reconstruction quality directly in the spectral domain. Below, we show full reconstructed scenes alongside per-pixel spectral radiance curves, comparing the true spectrum, our guided prediction, our prediction without guidance, and prior methods. Removing our inference-time guidance noticeably increases spectral uncertainty (shaded band) and error, confirming that guidance is essential for accurately synchronizing the independently generated patch predictions.
Uncertainty Estimates Correlate with Reconstruction Error
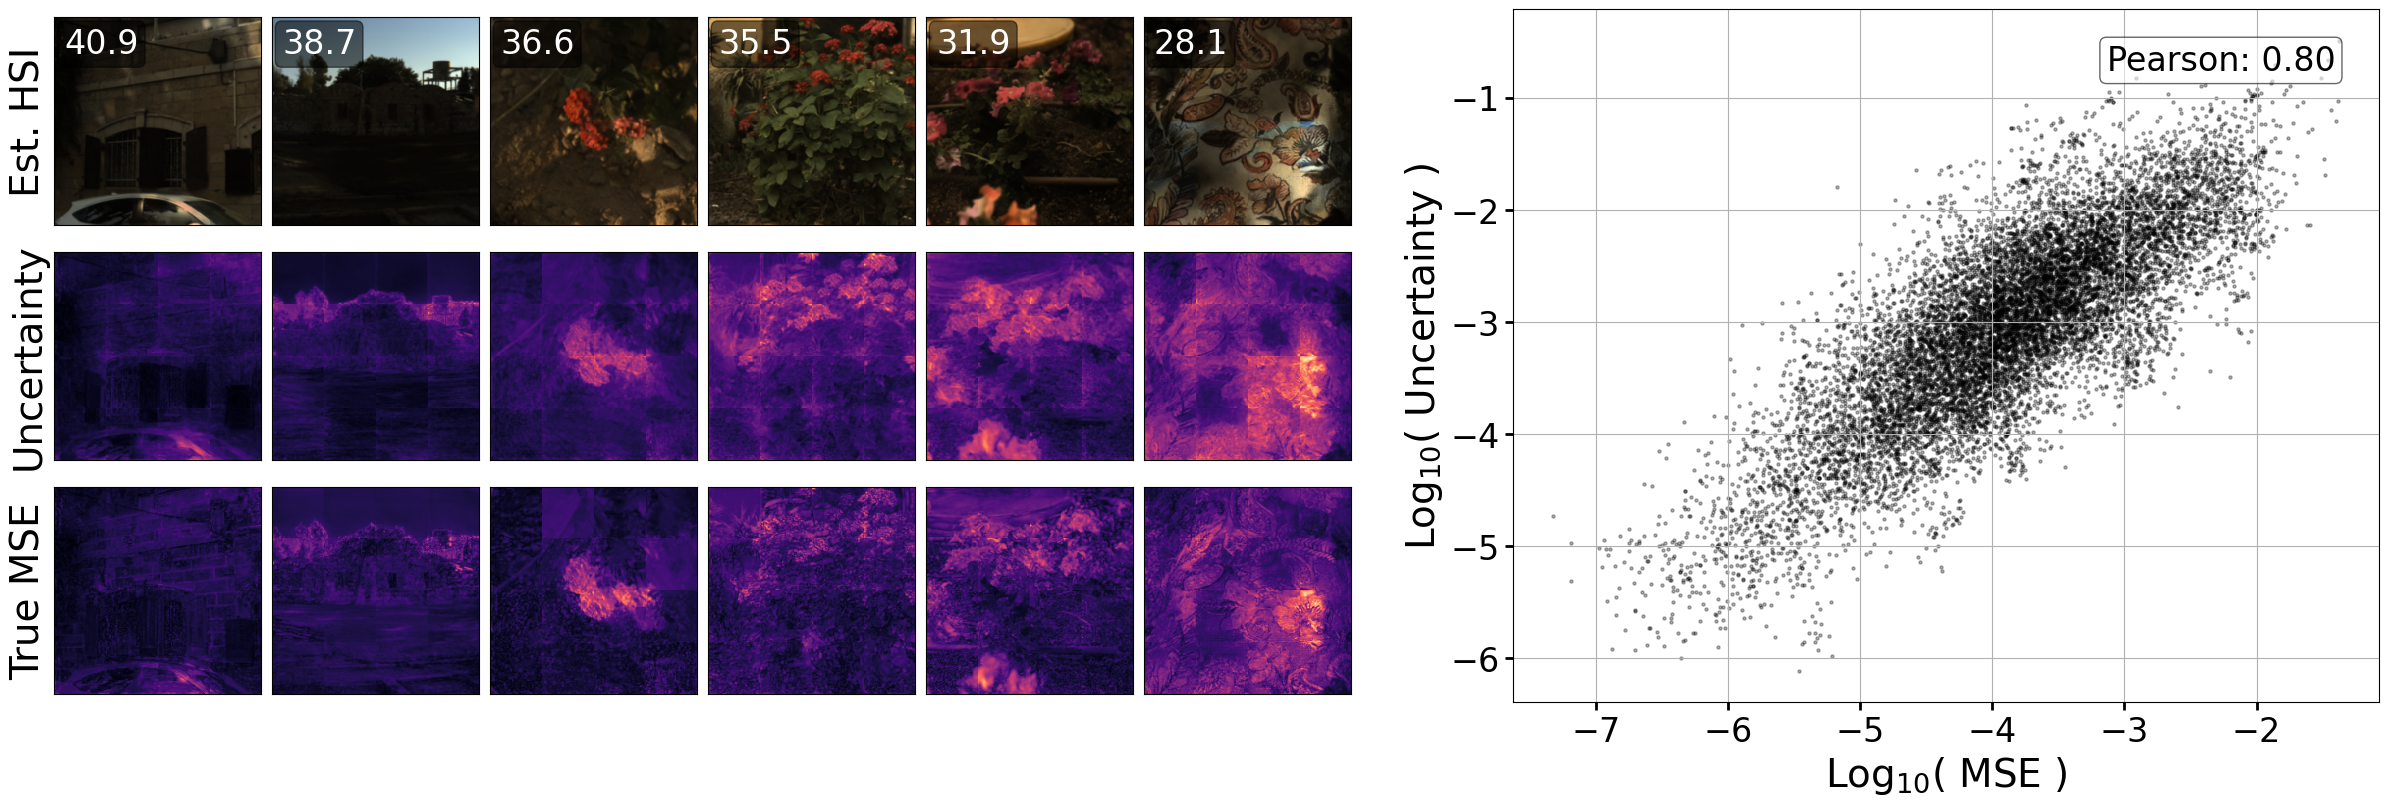
Because our model is a diffusion model, we can draw multiple independent hyperspectral reconstructions for the same measurement by resampling the initial noise seed. Computing the per-pixel variance across these repeated draws gives a spatial uncertainty map at no extra training cost. Comparing this uncertainty map to the true per-pixel reconstruction error (MSE against ground truth) across many test scenes, we find a strong correlation (Pearson coefficient 0.80). This shows the diffusion model "knows" where its predictions are least reliable, which is valuable for downstream, uncertainty-aware use of the reconstructions.
Cross-Dataset HSI Reconstructions on ICVL, Harvard, and CAVE Datasets
Our model is trained only on the ARAD1K dataset. To test generalization, we evaluate it directly on hyperspectral scenes from the ICVL and Harvard datasets with no additional fine-tuning, shown below alongside a metamerism stress test on the CAVE dataset.
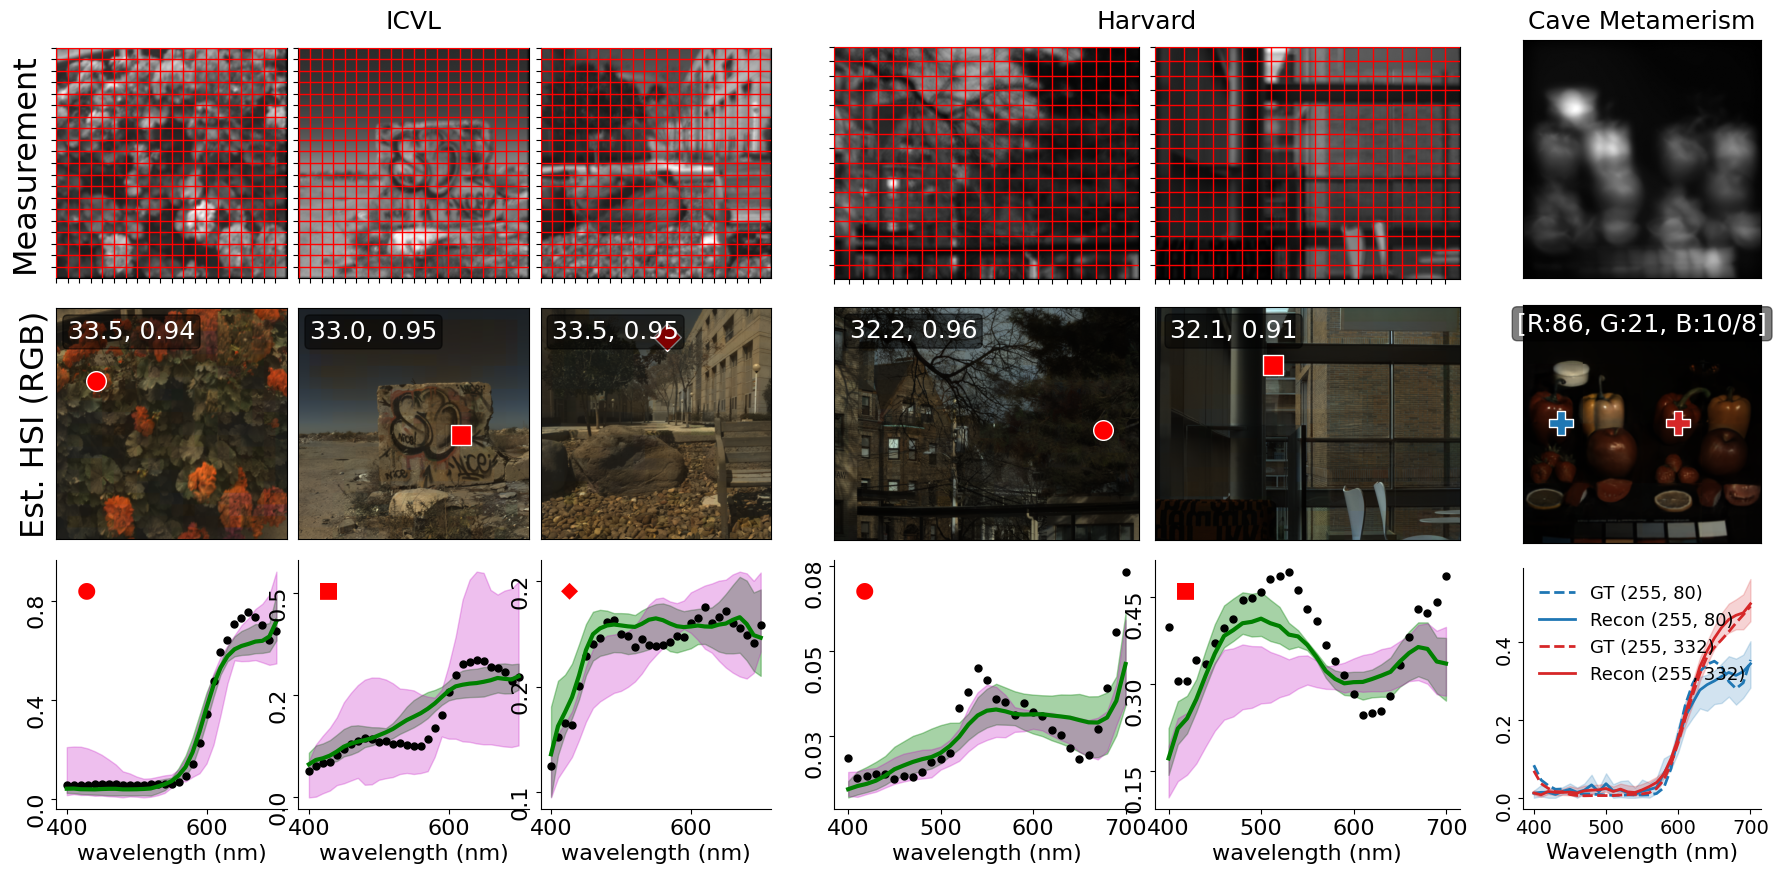
We stress-test spectral accuracy using a metamerism experiment: two patches of the CAVE dataset that appear as the same RGB color are rendered into measurements and reconstructed independently. Despite being visually indistinguishable in RGB, our model recovers their distinct underlying spectra, confirming that the reconstruction is driven by genuine spectral cues rather than color appearance alone.
Experimental Validation with a Physical Prototype Camera
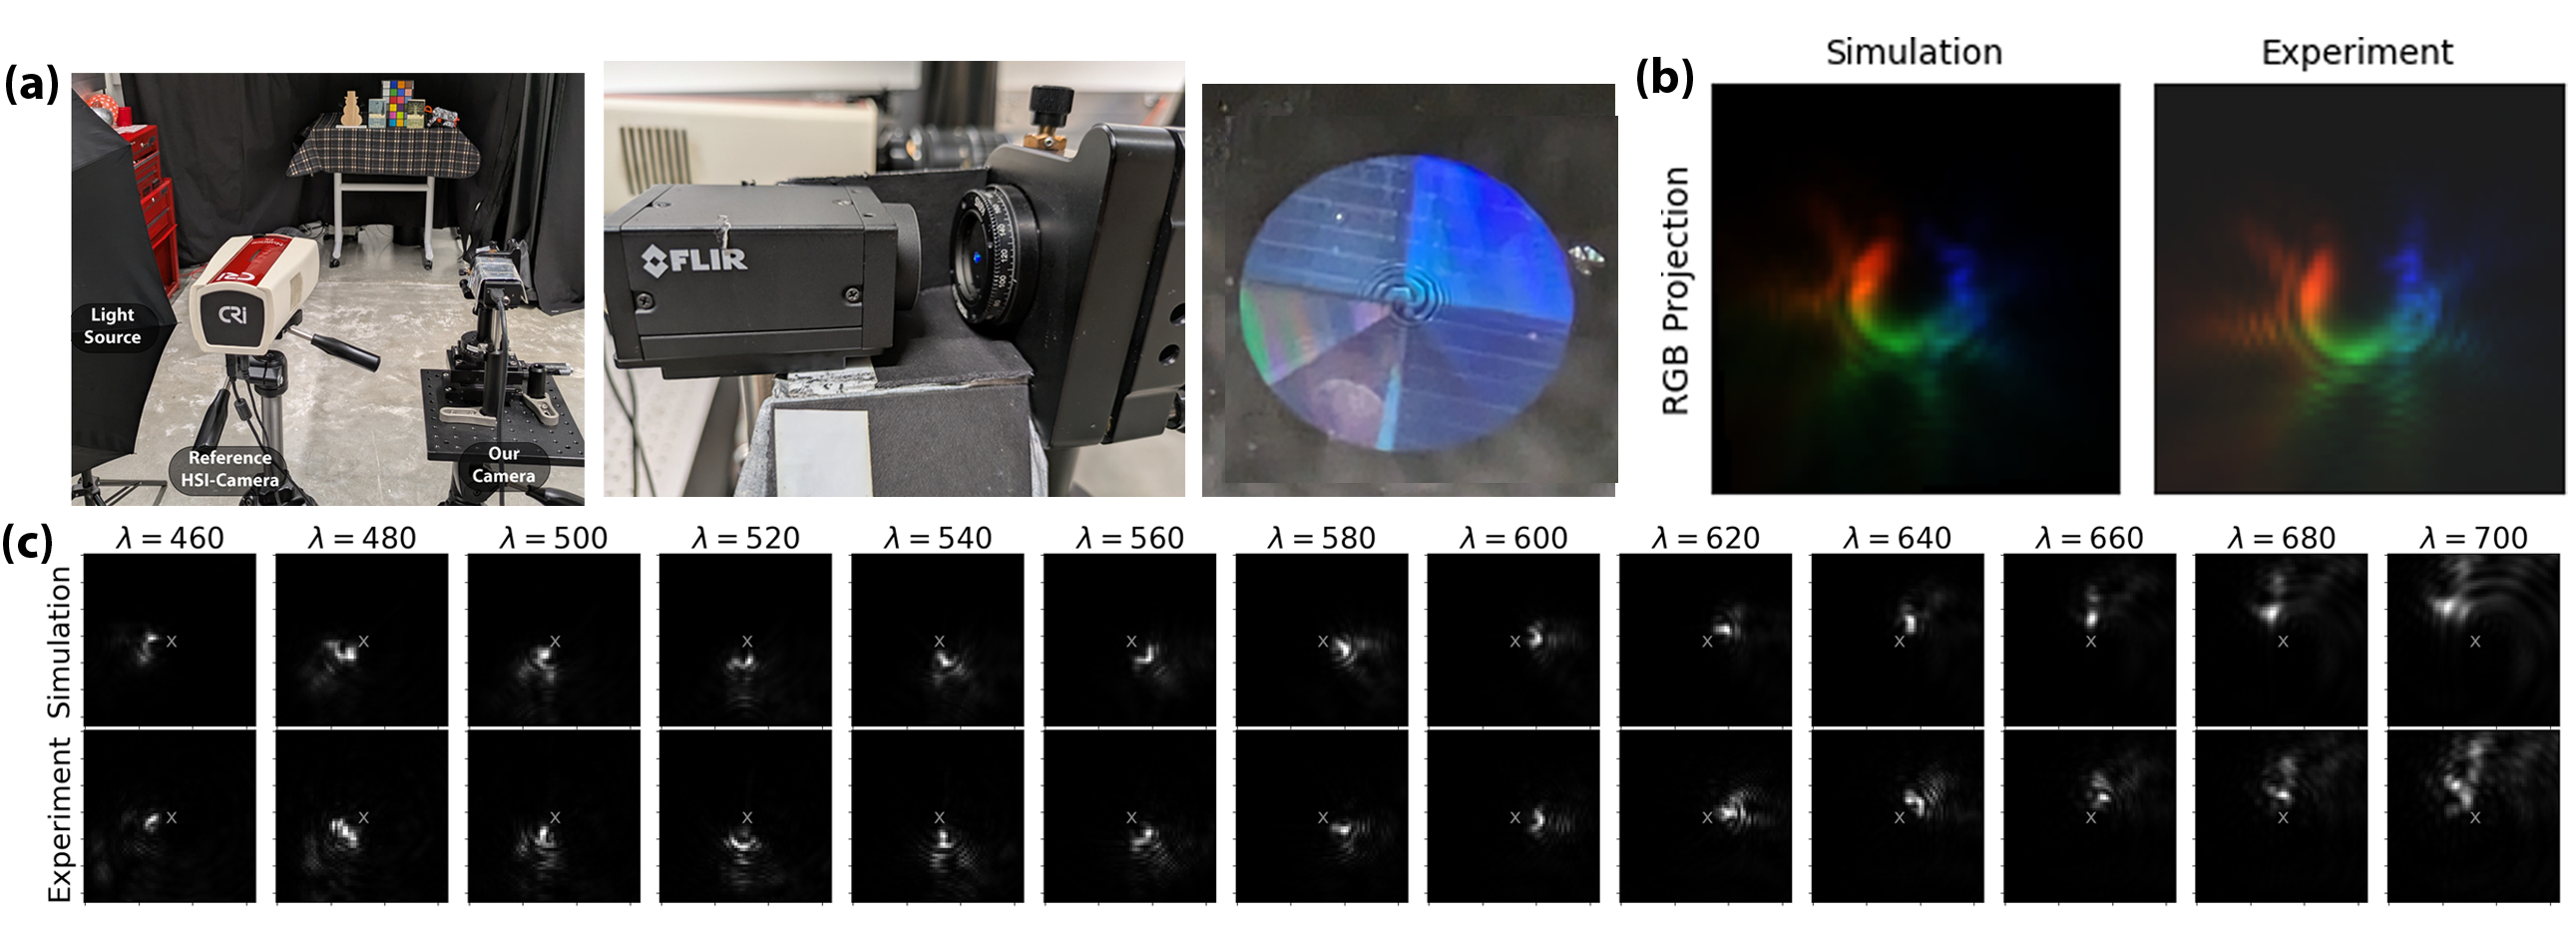
Beyond simulation, we build a prototype camera using a fabricated diffractive lens and a filterless grayscale photosensor, and use it to capture real tabletop scenes. Reconstructing hyperspectral images from these real measurements is more challenging than in simulation due to calibration errors between the true and modeled optical response. We find that our inference-time guidance, which enforces consistency with the measurement, significantly helps to overcome these calibration errors compared to reconstructing without guidance.